


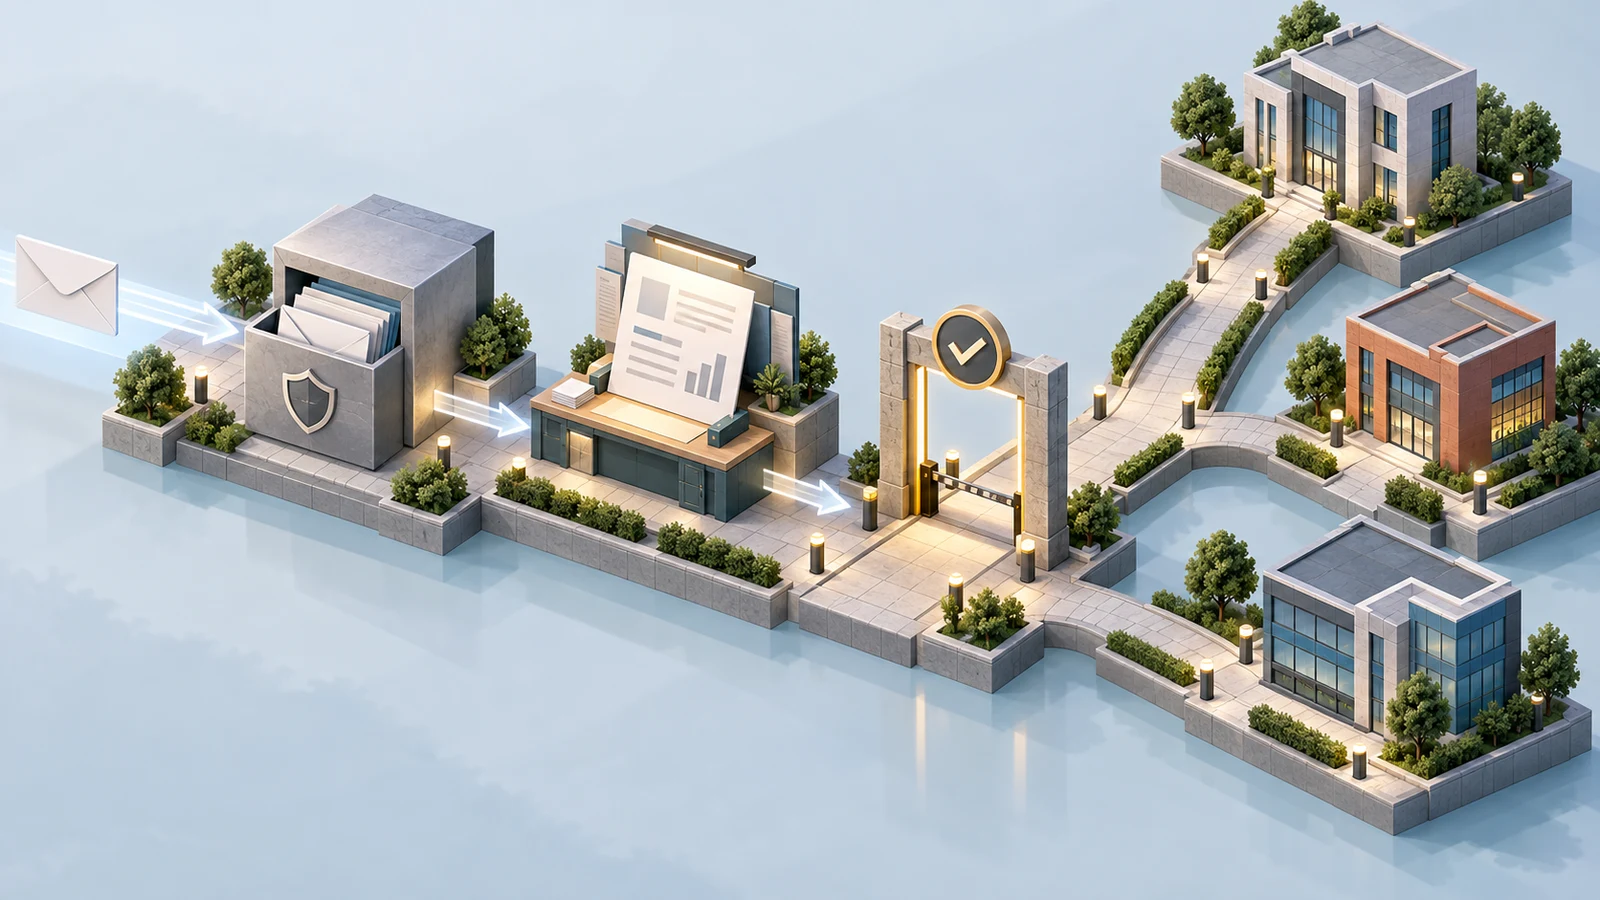
| Author: Abdullah Ahmed | Category: API Development and Integration
A service request arrives while the operations team is away from its desk. The CRM emits an event, a workflow reads the message, and an AI component proposes a category and draft response. By morning, staff should find a useful case ready for review. What they should not find is a duplicated ticket, an unexplained customer commitment, or a job that disappeared after an API timeout.
APIs, webhooks, and AI each solve a different part of this workflow. Webhooks notify your software that something happened. APIs let it retrieve information or request an operation. AI can interpret variable content and prepare a proposal. The surrounding application coordinates state, permissions, and recovery.
This distinction is the foundation of a dependable design. The example throughout this article is a service-request intake process connecting a CRM, an internal work queue, and a customer communication system. It is an illustrative architecture that you can adapt to your own supported interfaces and business rules.
Define the completed business outcome first
Decide whether the workflow should create a draft case, assign a team, prepare a reply, or send an approved message. These outcomes have different authority requirements. A vague objective such as handle incoming requests leaves too many decisions implicit.
Write the conditions for completion. A draft case might require a verified account, a source message, an allowed category, and a visible unresolved-question field. Sending a message additionally requires a recipient, final content, and confirmation from the communication service.
Separate useful partial outcomes from failures. If the CRM record is available but classification is unresolved, the system may still create a manual-review item. That can be a legitimate result rather than a reason to discard all gathered information.
Identify the process owner and the staff who will handle exceptions. Their ability to finish interrupted work is part of the architecture, not an operational detail to discover after launch.
Use events to start work, not to prove every condition
A webhook tells your application that the source emitted a particular event. Its payload may describe a historical transition, a snapshot, or only a reference to a changed resource. Check the provider's contract before deciding how much authority to give that payload.
For request intake, the event can trigger a current CRM lookup and evaluation of the case's eligibility. It should not automatically bypass account restrictions or create a second case because a similarly named event arrived again.
Document event types, account scope, supported payload versions, and delivery behaviour. Provider contracts differ. GitHub's webhook best-practice guidance, for example, covers validation, prompt acknowledgement, asynchronous processing, and delivery identifiers; use the equivalent guidance for the actual sender you integrate.
Plan a reconciliation path for missed work. Periodically compare eligible source requests with internal case records. Events provide timely triggers, while reconciliation helps discover omissions caused by configuration, outages, or implementation mistakes.
Create a durable intake boundary
The receiving endpoint should verify the request using the sender's supported mechanism, validate the envelope, and persist enough information to process it. Only acknowledge successful acceptance after the durable write succeeds.
Keep lengthy interpretation and downstream API calls outside the request-response deadline. A queue or persistent inbox lets the system absorb bursts and retry processing without making the sender wait for a model response.
Record a source-scoped event identifier, received time, type, payload reference, and processing state. Avoid retaining more sensitive message content than the workflow and diagnostic requirements justify.
Test failure at the storage boundary. If the database or queue is unavailable, the endpoint must behave according to the provider's failure contract. Returning success and dropping the event creates a gap that may remain invisible until a customer complains.
Model the workflow with explicit states
Useful states might include received, context pending, interpretation pending, review required, approved, execution pending, confirmed, and exception. Choose states that correspond to meaningful operational decisions rather than exposing every internal function call.
Persist transitions with the task identifier and relevant version information. A process restart should not require the model to infer from a transcript whether an action already happened.
Keep uncertain execution distinct from a confirmed failure. A timeout after submitting a message leaves the outcome unknown until checked. That state needs reconciliation, while a validation error may need a corrected proposal.
Define who or what may move the task between states. A reviewer can approve a specific proposal; a worker can report a confirmed API result; the model can suggest a category. These are separate authorities.
Gather context through limited read operations
The interpretation step may need the customer record, related open cases, and an approved knowledge source. Expose narrow read tools that return the fields relevant to the task rather than broad database access.
Enforce the initiating actor's or service account's permissions in the owning application. A model-supplied customer identifier is not proof that the workflow may access that customer's records.
Return clear result states such as found, ambiguous, forbidden, and temporarily unavailable. If every unsuccessful lookup becomes an empty answer, the model may invent missing context or repeat unproductive calls.
Include source links and freshness information where they affect the proposal. Staff reviewing a service request should know whether the account status was retrieved now or came from an older event snapshot.
Place AI at a bounded interpretation step
Ask the model to perform a specific task, such as propose one allowed category, extract requested dates, and draft a reply using approved information. Require a structured output that the application can validate.
Keep business decisions that have exact rules in ordinary code. Required approvals, account eligibility, and permitted transitions should not depend on the model's description of what seems reasonable.
Allow incomplete output. A request that does not provide enough information can produce an unresolved field and a clarification draft. Forcing every case into a complete answer encourages unsupported assumptions.
Treat incoming messages and retrieved documents as data. Their text must not expand the task, change credentials, or authorise a new destination. The execution layer should reject any operation outside the workflow's defined capabilities.
Validate the proposal before routing it
Check schema, allowed categories, required references, recipient identity, and any business constraints. Reject unknown fields or operations that could accidentally acquire meaning later in the pipeline.
Validate factual claims against available records where the workflow permits deterministic checks. A proposed response mentioning a confirmed appointment should refer to an actual appointment record, not merely a phrase in the customer's request.
Store the proposal version and source versions used. If a reviewer edits the draft, preserve the edited version as the one eligible for approval. A later model retry should not replace it silently.
Classify failures by the next action they require. Invalid model structure may justify a bounded retry; missing customer information may require clarification; a forbidden action should stop. One generic retry policy is not sufficient for all three.
Build a review handoff that contains the decision
Show the reviewer the original request, relevant source facts, proposed category, draft response, and unresolved questions. Avoid making staff reconstruct the task from a sequence of tool messages.
Make approval refer to a concrete action and content version. If the recipient or message changes afterward, the earlier approval should not authorise the new operation automatically.
Recheck current state at execution. The customer may have replied, another employee may have resolved the case, or the account may no longer be eligible. A correct proposal can become stale while waiting for review.
Measure review effort and queue age. If staff cannot assess proposals efficiently, the workflow may move the bottleneck rather than reduce it. Better evidence presentation can be more valuable than producing longer drafts.
Protect every external action from duplication
Repeated delivery and worker retries are normal conditions to design for. Use a concurrency-safe event inbox to prevent duplicate processing, and a separate stable operation key for consequential downstream actions.
Event identity and business identity are not always the same. Two distinct events may describe one request that should create only one internal case. Define the domain key that makes a repeated business operation recognisable.
Use the destination's supported idempotency facility where available. If it offers no such mechanism, investigate its status or lookup options and design a conservative recovery procedure for uncertain results.
Do not tell the model to remember that it already sent a message and rely on that alone. The application should record the intent, submission reference, and confirmed outcome so duplicate protection survives restarts and new conversations.
Handle delays and stale events deliberately
A request may be updated several times before processing catches up. Decide whether the workflow needs every historical transition or only the latest source state. The answer affects how you treat older events.
Where the provider exposes a meaningful resource version, use it according to the contract. Do not infer ordering from local arrival time or arbitrary identifiers. A delayed event can arrive after a newer state is already processed.
For intake, a current-state lookup may let the system recognise that the case has already been resolved. It can record the event as requiring no further action rather than reopening work unnecessarily.
Include source and processing timestamps in diagnostics. They help distinguish delayed delivery from a slow internal queue and support a useful explanation when staff investigate why a case appeared late.
Budget for bursts, rate limits, and model latency
The workflow's throughput is constrained by its slowest dependency. A CRM lookup limit, a model timeout, or a communication service quota can cause a backlog even when the webhook receiver is healthy.
Control concurrency and retries centrally. Apply provider-appropriate delays and limits, and avoid allowing each model run to retry independently without coordination. A temporary outage should not produce a surge that prolongs the problem.
Set per-task limits on model calls, elapsed time, and data volume. When those limits are reached, preserve useful work and route the case to an exception state. Infinite persistence is not a reliable operating policy.
Measure time from source event to accepted business outcome. Endpoint response time and model generation time are useful diagnostics, but neither captures the review queue or downstream execution delay.
Make recovery a supported staff workflow
Provide an exception queue with the affected customer, task state, failure category, attempt history, and a safe next action. Different issues should reach people who can resolve them, rather than all becoming engineering tickets.
A corrected mapping should allow replay through the same validation and duplicate controls as normal processing. Special repair paths that bypass rules can create more serious inconsistencies than the original failure.
Keep a manual route available for essential work. Staff should be able to create or resolve a case through the existing application when the AI component is unavailable, with the automated workflow recognising the resulting state later.
Practise recovery before launch. Stop a worker, interrupt an API response, and change a source record while approval is pending. Verify that the system preserves work, avoids duplicates, and explains the final state accurately.
Test the complete chain with realistic fixtures
Unit checks for schemas and permissions are necessary, but end-to-end scenarios reveal timing and coordination problems. Include duplicate events, malformed payloads, invalid signatures, missing records, conflicting messages, and partial downstream success.
Evaluate the AI step on representative request language and difficult examples. Assess category correctness, unsupported claims, and clarification quality separately from execution reliability.
Check the actual destination state after each scenario. A friendly completion response is not evidence that the intended action occurred. Conversely, a completed action followed by a lost response should not trigger another action.
Version the event fixtures, tool contracts, model configuration, and expected outcomes. When any dependency changes, the team should be able to rerun the relevant cases and identify what changed.
## Write an operation ledger staff can trust
Keep a compact ledger of consequential actions linked to the workflow task. It should identify the proposed operation, approval where required, submission reference, and confirmed result. This record is more useful for recovery than a transcript in which the assistant repeatedly says what it intends to do.
Use the ledger to answer practical questions: was a case created, which customer message was submitted, and is the destination outcome known? Protect access to the underlying content while allowing authorised staff to inspect the state.
When a task is replayed, compare its operation references with the ledger before issuing new writes. A new model response should not erase the fact that an earlier attempt already completed part of the work.
Agree on a change process across teams
The CRM, work queue, and communication system may have different owners. Record who maintains each interface contract and how breaking changes are communicated. A payload adjustment in one application can affect several stages of the workflow.
Keep representative contract fixtures with the integration and run them when a dependency changes. Include error responses and asynchronous status behaviour, not just successful examples.
When changing the model or interpretation prompt, check that the proposal still satisfies the downstream contract. A more detailed output can be an improvement for readers while exceeding a field limit or changing a category value unexpectedly.
A small release note describing the changed capability, affected event types, and validation performed helps operations understand what to watch after deployment.
Release one event-to-outcome path
Start with a single event type and a useful internal outcome, such as a reviewed draft case. Observe the real mix of requests and exceptions before adding automatic customer communication or more connected applications.
Agree on release criteria covering outcome quality, review effort, backlog handling, and recovery. The system should be understandable to the people operating it under imperfect conditions, not only to the developers demonstrating it.
A concise workflow contract is a strong first deliverable: trigger, authoritative sources, interpretation task, allowed actions, approval boundary, and recovery owner. Once that contract is clear, APIs and webhooks can connect the pieces while AI contributes at the step where interpretation actually helps.
Author
With over 15 years of diverse experience spanning front-end and back-end development, UI/UX design, project management, integration, testing, and ongoing support for business applications, I specialize in transforming ideas into seamless digital solutions. I’m committed to leveraging my expertise to drive innovation and contribute meaningfully to the tech community.