


| Author: Abdullah Ahmed | Category: API Development and Integration
The automation approved a supplier update, sent it to the purchasing system and then lost the connection before receiving a response. The worker retried. Later, two confirmation messages appeared, and nobody could tell whether the supplier record had been changed once or twice. The language model had interpreted the request correctly; the surrounding workflow had failed to manage an uncertain outcome.
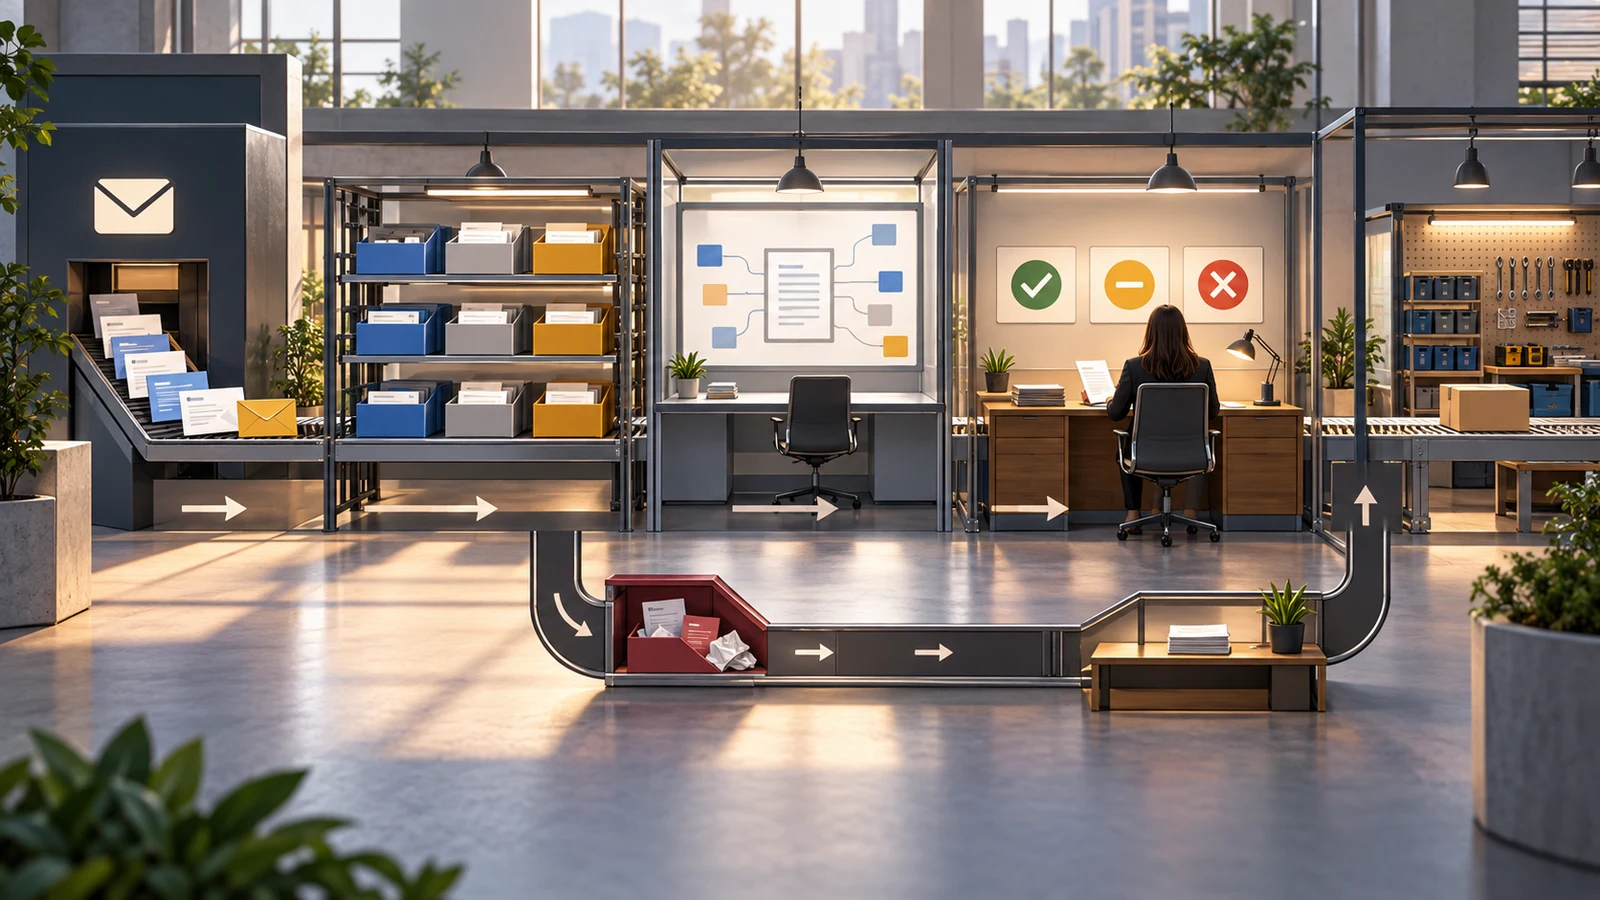
Reliable AI automation depends on the same operational disciplines as other business integrations, with an additional boundary around model-generated proposals. APIs enforce business operations, webhooks announce events, queues hold work and approval records capture authorised decisions. Connecting those components requires explicit rules for identity, state, retries and recovery.
We will use a fictional supplier-maintenance workflow as a running example. An incoming request asks to change a delivery contact and address. AI extracts the proposed changes, an employee reviews them and an application updates the purchasing platform. The design must remain understandable when messages repeat, approvals become stale or a downstream service stops responding.
Model the business operation before its messages
Create one durable operation record for the requested change. Give it a stable identifier, an account or tenant boundary, the source reference, the affected supplier and a clear lifecycle. Useful states might include received, interpreting, awaiting review, approved, executing, completed, rejected and requiring investigation. Define the permitted transitions rather than letting arbitrary components assign status strings.
Messages represent attempts to advance that operation. They are not the operation itself. Several queue deliveries or webhook notifications can relate to the same requested change. Keeping the business record separate lets the application answer what happened without assuming that every message corresponds to a new action.
Store relevant timestamps and version identifiers. A review completed at one time may refer to an earlier supplier record and proposal. Those references allow the executor to check whether the decision is still applicable. They also help an operator distinguish slow processing from work that is waiting legitimately for a person or external event.
Accept events through a narrow entry point
At the webhook endpoint, verify the sender using the provider's documented mechanism and validate the event envelope before admitting work. Preserve the bytes required for signature verification, apply appropriate request limits and associate the event with the correct account. A valid signature establishes a source relationship; it does not replace your business permission checks.
Persist an accepted event or durable work record before acknowledging it. Keep expensive model calls and downstream changes out of the request handler where possible. If the endpoint returns success before securing the work, a process crash can lose an event that the sender believes was delivered. If persistence fails, respond according to the provider's retry contract.
Understand the actual delivery behaviour of each integration. Stripe's webhook guidance, for instance, covers duplicate delivery, signature validation and events arriving without guaranteed order. Verify equivalent details for your provider and design around them. Testing only a single successful notification leaves the most consequential behaviours unexplored.
Deduplicate at more than one level
An event identifier helps recognise a repeated delivery of the same event. A business-operation identifier helps recognise multiple events or requests that refer to the same intended change. Use both where appropriate. A provider can issue different event types about one object, and a customer can resubmit a request through another channel.
Scope identifiers carefully. Include the provider or account boundary when uniqueness is not global, and enforce the relevant uniqueness rule in durable storage. Two workers checking an in-memory list before either writes to it can both proceed. The database or receiving service should arbitrate the race using constraints or another suitable atomic mechanism.
Do not deduplicate solely by matching request text. Two identical-looking address changes for different suppliers are distinct operations, while differently worded messages may describe the same request. Link them using explicit business references and reviewed associations. Keep duplicate detection explainable so staff can correct a mistaken merge without losing the original evidence.
Use queues to control work, not hide it
A queue decouples event acceptance from processing capacity. Configure worker concurrency around the downstream systems' limits and the application's operating budget. If model calls become slow, accepted requests can remain durable while the service reports a pending state. The queue does not eliminate waiting; it makes waiting manageable and observable.
Assume a worker can stop at any point. Work may become available again after a lease or visibility period expires, depending on the chosen queue. Acknowledge a message only after its processing outcome has been recorded appropriately. Long-running tasks may need lease renewal or smaller stages so that another worker does not begin the same action unexpectedly.
Track queue age alongside depth. Ten old supplier changes can be more concerning than a hundred new requests during a planned import. Separate workloads when their service expectations or resource needs differ. A bulk content job should not consume every worker needed for an urgent operational update simply because both happen to use AI.
Keep interpretation separate from execution
Ask the model for a structured proposal containing the fields to change, supporting evidence and any unresolved ambiguity. Validate that proposal against a schema and the business object's allowed fields. A fluent explanation does not establish that the supplier identifier exists or that the requested address is complete.
Give the interpretation stage only the access it needs. It may retrieve relevant supplier information, but the application should control what can be changed and under whose authority. Treat incoming messages and attachments as untrusted content, including any text that appears to instruct the assistant to bypass review or call a different tool.
Persist the proposal with the model configuration and input references needed for diagnosis, within the organisation's data-handling policy. Avoid placing unnecessary personal details in general logs. Operators usually need identifiers, state transitions and concise error categories; authorised reviewers can open the relevant protected evidence when investigating a specific case.
Make approval a versioned decision
Show the reviewer the current supplier values, proposed replacements and supporting request. Identify exactly what approval will authorise. A generic approve button beside a generated summary leaves too much room for disagreement about scope. The employee should be able to correct or reject the proposal and record why the request cannot proceed.
Bind approval to the proposal version, target record version, reviewer identity and any expiry conditions. If the delivery address changes after review, the earlier approval should not silently cover the new proposal. Likewise, if another employee updates the supplier record, the executor must check whether the approved patch remains valid against the newer state.
The executor should recheck the reviewer's applicable authority and the operation's state at execution time. An approval that was valid when clicked may no longer be usable after reassignment or cancellation. Store the decision as durable application data, and use a controlled state transition to claim execution so two workers cannot independently act on the same approval.
Close the database and messaging gap
A common failure occurs when an application saves an approved state and then crashes before publishing the execution message. Reversing the order creates the opposite problem: a worker can receive a message for an approval that was never committed. These are two writes to separate systems, so ordinary sequential code does not make them atomic.
The transactional outbox pattern described by AWS addresses this dual-write problem by storing the business change and an outgoing event within the same database transaction, then publishing the event through a separate process. Consumers still need to handle duplicates. The pattern provides a recoverable handoff; it does not make every downstream action exactly once.
Use this approach where the failure risk warrants the additional component. Monitor the outbox publisher and the age of unpublished entries, and retain enough information to investigate delivery. A simpler workflow using one transactional data store may not need the same machinery. Choose the design from the actual consistency boundary rather than adding infrastructure by habit.
Design retries around the operation's effect
Distinguish failures that may succeed later from failures that require a changed request or human decision. A temporary service outage can justify retrying with bounded backoff. An invalid supplier reference needs correction. An authentication failure may require operator action. Repeating every failure indefinitely wastes capacity and obscures the cases that need attention.
Use a stable idempotency key for the same intended downstream operation when the API supports it, following that provider's documented scope and retention rules. Reusing the key for a changed request can be incorrect; generating a fresh key for every retry defeats its purpose. Record the relationship between the key, proposal version and business operation.
Limit attempts and total elapsed retry time, then move unresolved work into a visible investigation path. Introduce spacing between retries to avoid a surge when a service recovers. Preserve the original failure and subsequent attempts so an operator can understand the sequence. A final error message alone often hides whether the remote system may already have acted.
Treat timeouts as uncertain outcomes
A timeout tells you that a response did not arrive within the allowed period. It does not prove the remote change failed. Before retrying a potentially non-idempotent operation, query the receiving system using the recorded reference where possible. Compare the actual state with the intended change and record the reconciliation result.
Some APIs offer no suitable lookup or idempotency mechanism. In that case, a cautious workflow may stop for investigation rather than automatically repeat a consequential write. Make this limitation part of integration planning. It can influence vendor selection, the allowable automation scope and the amount of operational support the business must provide.
Define what evidence is sufficient to mark completion. An HTTP success response, a returned operation identifier and a later confirmed state can mean different things depending on the API. Use the provider's documented semantics and the business's required outcome. Avoid presenting a queued remote job as a completed supplier update before its result is known.
Handle ordering and concurrent changes explicitly
Two approved requests can target the same supplier. If both were prepared against an earlier record, applying them in arrival order may overwrite a newer decision. Use version checks, conditional updates or a suitable per-object ordering strategy. Where changes affect different independent fields, define whether they can be safely merged and who resolves conflicts.
Do not assume event timestamps alone establish the correct execution order. Clocks, delivery delays and different event sources complicate that interpretation. Prefer authoritative object versions or a documented event sequence when available. If the integration cannot establish ordering reliably, retrieve current state and decide whether the requested transition still makes sense.
Cancellation also races with execution. Specify when a request can be withdrawn and what happens once a downstream write has begun. An accepted cancellation request should not imply a completed reversal. Give the user a precise state and, where necessary, initiate a separate authorised corrective operation with its own evidence and outcome.
Build recovery tools before broad rollout
Operators need a view of the operation, related events, proposal, approval and downstream references. Provide narrowly scoped actions such as retry interpretation, request fresh approval, reconcile remote state or cancel pending work. Avoid a universal replay button that can resend old writes without checking whether their effects already exist.
Before a manual retry, show what will run and why it is considered safe. Record the operator, reason and resulting attempt. Protect recovery actions with appropriate permissions, particularly when they can change customer or supplier data. Operational convenience should not create a route around the same business controls used by the normal workflow.
Retain a way to pause execution while continuing to accept or inspect requests, if that matches the service's needs. During an incident, the team may want to preserve incoming work without making more changes. Show the paused state to staff and manage expectations for pending requests. A restart should reconcile existing work before releasing a large backlog.
Test failures as complete business scenarios
Simulate a crash after event persistence, after approval commit, after the remote write and before the worker acknowledgement. Deliver the same event repeatedly and in a different order. Change the supplier record while approval is pending. The expected result should specify durable records, remote effects and user-visible messages for each scenario.
Use a controlled test integration or sandbox with representative response behaviours. A mock that always returns immediate success cannot validate timeout reconciliation or duplicate handling. Include malformed model output, ambiguous evidence and a reviewer changing the proposal. Verify that these conditions remain contained within the intended stage and do not accidentally trigger execution.
Define release criteria around business outcomes: no unauthorised writes in the test set, recoverable uncertain outcomes, explainable state transitions and an operator able to resolve the planned failure cases. Add performance and cost limits appropriate to expected traffic. Revisit the affected scenarios when tools, permissions, prompts or downstream contracts change.
Make reliability visible to the business
Report completed operations, waiting approvals, oldest pending work, retries and cases requiring investigation. Separate interpretation failures from integration failures so the team can direct improvements correctly. Track review effort and recovery time alongside model usage; these costs determine whether the automation is practical to operate.
Start by drawing one operation from its incoming event to its confirmed remote effect. Mark every point where the process can stop and identify the durable evidence available for recovery. If the team cannot explain what happens after a lost response or stale approval, resolve that gap before widening access. Reliable automation grows from those explicit decisions, one business transition at a time.
Author
With over 15 years of diverse experience spanning front-end and back-end development, UI/UX design, project management, integration, testing, and ongoing support for business applications, I specialize in transforming ideas into seamless digital solutions. I’m committed to leveraging my expertise to drive innovation and contribute meaningfully to the tech community.