


| Author: Abdullah Ahmed | Category: API Development and Integration
A customer pays an invoice, but the account still appears overdue in your service portal. The payment platform knows what happened. Your application will not know until its next scheduled check, or until somebody investigates the complaint. This gap is a common reason businesses introduce webhooks.
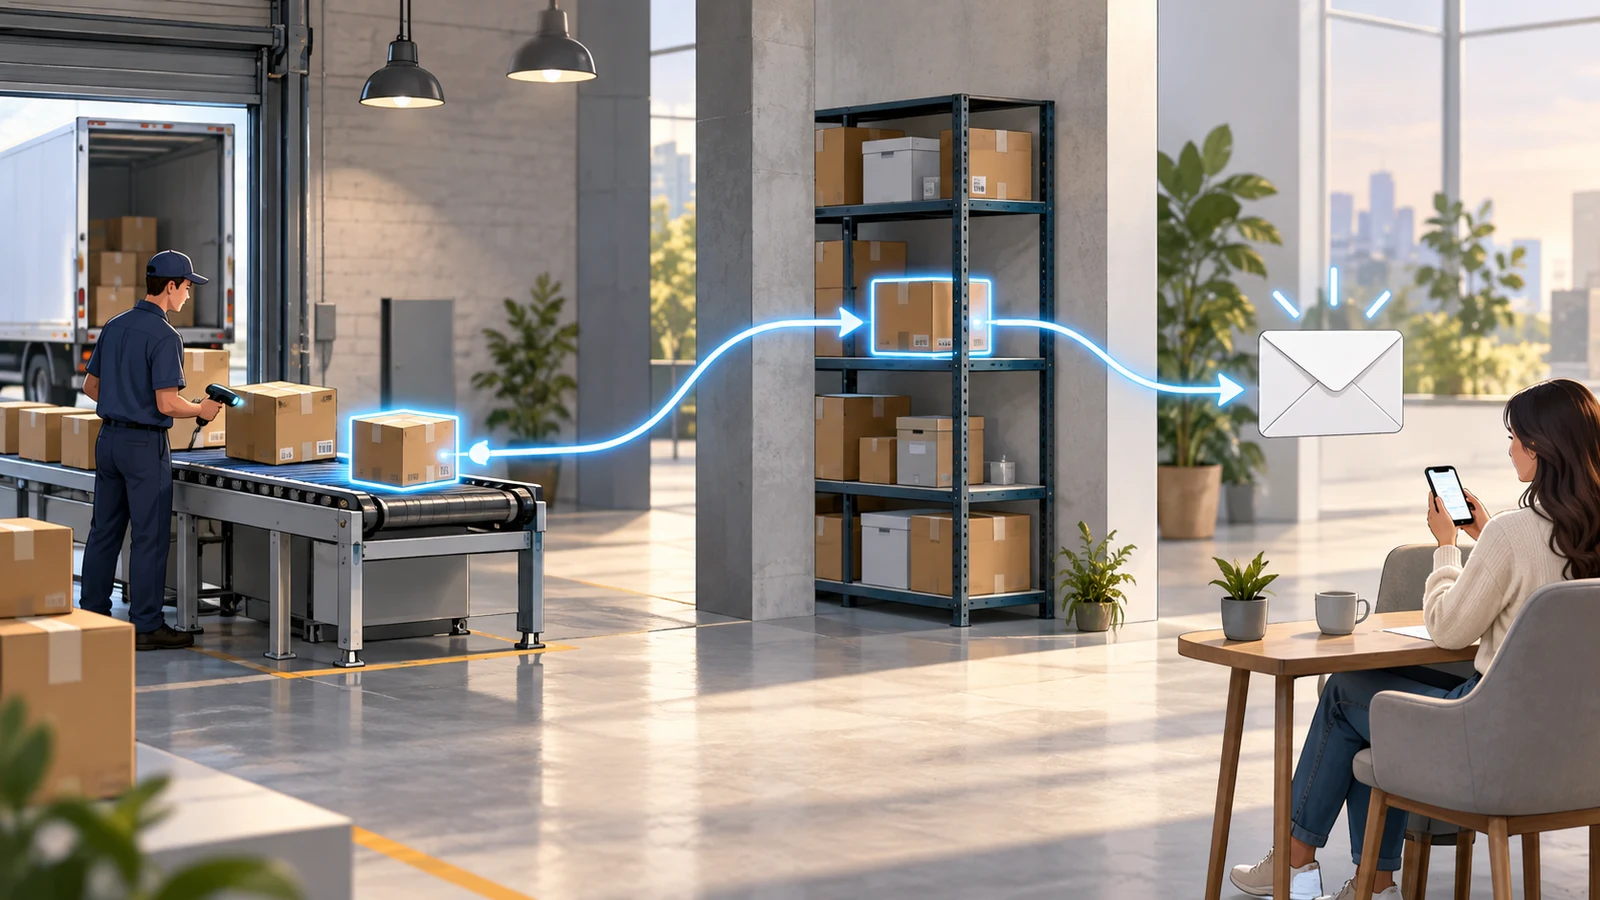
A webhook lets one system notify another when a relevant event occurs. Instead of repeatedly asking whether anything changed, your application receives an HTTP request describing an event. That notification can start a business workflow: updating an account, preparing an order, refreshing a record, or notifying a member of staff.
The attractive part is speed. The difficult part is making the resulting workflow dependable when messages arrive twice, arrive late, or cannot be processed immediately. This guide explains the decisions behind a useful webhook integration, using an illustrative order-to-fulfilment process rather than a claimed customer implementation.
Define what real time means for the business
For many business integrations, real time means responding soon enough that people do not notice an operational delay. It does not imply a hard timing guarantee. Network conditions, provider delivery policies, and your own processing queue all affect when the change becomes visible.
Write down a useful target for the actual workflow. A warehouse may need paid orders available before its next picking cycle. An account portal may need a clear pending state while access is being provisioned. These are different requirements even if both use the same event technology.
Measure the elapsed time from the source event to the completed business action. Measuring only how quickly the webhook endpoint responds hides delays in downstream work. A healthy endpoint can acknowledge messages promptly while a stalled worker leaves customers waiting.
Also decide what users should see during that interval. A payment received message and a provisioning in progress message can be more accurate than immediately declaring an account fully active. Product wording should reflect the state the application can verify.
Choose the event that actually authorises the action
An order being created is different from payment being confirmed. A shipment label being generated is different from a parcel leaving the warehouse. Connecting the wrong event to an action can produce a workflow that operates quickly and still makes the wrong decision.
Ask the source system owner to explain event semantics. Is the event emitted before or after a transaction commits? Does it describe a complete resource or only the fields that changed? Can the state change again before the receiver processes the notification?
For fulfilment, define the business conditions explicitly. The application might require confirmed payment, an accepted order, and available inventory. A webhook can prompt evaluation of those conditions without replacing them. The warehouse command should be issued only when the current order satisfies the agreed rules.
Record who owns each fact. The payment service owns payment status; the commerce application owns the order; the warehouse owns dispatch confirmation. This prevents an integration from treating a convenient local copy as authoritative for every decision.
Understand webhooks alongside polling
Polling remains useful when a provider offers no event subscription or when a periodic snapshot is sufficient. A reporting task that runs once overnight may not benefit from continuous event delivery. The choice should follow the required freshness and the supported provider interface.
Webhooks are especially useful when changes are intermittent and action should follow promptly. They can avoid repeated requests that mostly return unchanged data. Their operational cost moves toward receiving, validating, queuing, and reconciling notifications.
The two approaches can coexist. Use events to initiate timely work and a scheduled reconciliation job to find records that did not reach the expected state. Reconciliation should compare business facts, such as paid orders without a fulfilment record, rather than merely count HTTP requests.
Avoid claiming that the event channel guarantees perfect synchronisation. A dependable design makes missed work discoverable. That capability matters during deployments, credential problems, provider outages, and mistakes in event subscription configuration.
Build a small receiving boundary
The public endpoint should have a narrow responsibility: verify that the request is acceptable, capture it durably, and respond according to the provider's contract. Long-running activities belong behind that boundary, where they can be retried and observed separately.
A typical flow is receipt, signature validation, minimal envelope validation, durable inbox or queue write, and acknowledgement. Business processing then runs asynchronously. If durable storage fails, do not report successful acceptance and silently lose the event; use the provider's documented failure response behaviour.
For example, Stripe's webhook documentation describes signature verification, duplicate event handling, and delivery ordering considerations. Those details are provider-specific: confirm the exact contract for every service you connect, including acknowledgement deadlines and retry behaviour.
Keep the original event identifier, event type, source account, received time, and processing state. Retain payload content only to the extent your operational and data-handling requirements justify it. Logs should offer useful diagnostics without becoming an uncontrolled copy of customer information.
Verify origin before trusting the payload
A public URL is not proof that the caller is your payment or shipping provider. Implement the provider's supported verification mechanism and use its maintained library where appropriate. Validation must happen before the payload can initiate business changes.
Some signing schemes depend on the exact request bytes. Middleware that parses and reserialises JSON can change those bytes, so design the receiving path around the documented requirements. Test with realistic signed fixtures and the provider's supported testing facilities.
Separate secrets for development and production, and define how they are rotated. A rotation procedure should explain any overlap period, where credentials are stored, and how operators can tell that the new secret is working. Never print reusable credentials into troubleshooting output.
Verification also needs replay considerations. Follow the provider's timestamp and tolerance guidance where available, and maintain business-level duplicate protection. A correctly signed message can still be a repeated delivery of an event you have already processed.
Make repeated delivery safe
Imagine the worker reserves inventory successfully, then crashes before recording completion. When it processes the event again, it must not reserve a second set of stock. Protecting only the HTTP endpoint does not solve failures inside the business workflow.
Store a unique event identity within the appropriate source and account scope. Use database uniqueness or an equivalent concurrency-safe mechanism; a separate check followed by an insert can race when two workers handle the same event together.
Distinguish event duplication from operation duplication. Two different event identifiers might refer to the same business transition. A fulfilment record can also need a unique order or shipment operation key, depending on the rules for partial shipments and replacements.
When calling an external service, use its supported idempotency mechanism if available. If the call times out after the remote action may have succeeded, investigate the operation using its reference before blindly sending it again. The uncertainty concerns the outcome, not merely the failed connection.
Handle late and out-of-order information
A customer changes an order twice, and the older update reaches your worker after the newer one. Replacing the local record with whichever payload arrived last could restore stale information. Delivery order and business version order are separate concepts.
Where supported, compare a resource version or sequence associated with the source's actual state. Do not invent ordering guarantees from event identifiers or local receipt timestamps. If the provider supplies no usable ordering information, fetching the current resource may be a better response to a change notification.
Fetching current state also has trade-offs. It introduces another API call, requires credentials and rate-limit handling, and may return a state newer than the event. Decide whether your workflow needs the historical transition or simply the latest authoritative state.
Model important transitions explicitly. An order that has already shipped should not move backward into awaiting fulfilment because an older paid event arrived late. Exceptions such as refunds and returns should have their own business paths instead of being interpreted as generic status replacements.
Separate retryable failures from decisions requiring help
A temporary network error may justify another attempt. A missing customer mapping, invalid product reference, or forbidden state transition usually needs a different response. Retrying every failure indefinitely wastes resources and obscures the work somebody must resolve.
Use bounded retries with delays appropriate to the dependency. Put exhausted or non-retryable work into an inspectable exception state. Capture the reason, affected business record, attempt history, and suggested next step without exposing unnecessary payload details.
Give operations staff a supported way to correct mappings and replay eligible events. A replay should pass through the same safeguards as normal processing. A special repair button that bypasses validation can turn a manageable integration incident into a data problem.
Clarify ownership before launch. The software team may maintain the queue, while finance resolves unmatched invoices and warehouse staff resolve unavailable stock. Route failures to people who can make the required decision, with enough context to avoid repeated handoffs.
Observe the business backlog
An integration dashboard should answer whether work is progressing. Useful measures include the age of the oldest unprocessed event, failures by event type, the number of records awaiting intervention, and the elapsed time to the final business outcome.
Raw delivery volume is helpful for capacity planning but ambiguous as a success metric. A sudden increase might represent more orders, repeated retries, or an accidental subscription to unnecessary events. Compare traffic with business activity and duplicate rates.
Use a correlation reference that links the event, internal job, local record, and downstream request. This lets an operator follow one order without searching unrelated logs. Protect the diagnostic interface with access controls suitable for the information it exposes.
Alert on conditions that justify action. A brief recoverable retry may belong in a metric; a growing backlog close to the warehouse cut-off deserves attention. Define escalation around the business deadline and the available recovery window.
Test the uncomfortable delivery cases
The happy path proves that a sample message can travel through the system. Before release, also exercise duplicate deliveries, simultaneous workers, stale events, unsupported event versions, invalid signatures, queue failure, and downstream timeouts with uncertain outcomes.
Use an isolated environment with representative records. Include an order that has been cancelled, an account that has been removed, and a payment that no longer satisfies the fulfilment rules. The result should be an understandable business decision rather than an unhandled exception.
Test recovery as a workflow. Stop a worker, send events, restore it, and verify that the backlog drains without duplicate effects. Reconcile the resulting records against the source. This checks the path staff will depend on during an actual interruption.
Keep contract fixtures versioned with the integration. When a provider introduces a payload change or your team upgrades its client library, rerun the relevant cases. An event name staying the same does not guarantee that every surrounding assumption remains valid.
## Agree on version changes and release ownership
A webhook integration has two release calendars: yours and the provider's. Record the subscribed event types, payload version where applicable, account scope, and the person who owns configuration. An undocumented setting in a provider dashboard can be just as important as the receiving code.
When adding an event type, decide whether existing workers can handle it safely. Unknown types should follow a deliberate policy rather than crash the entire receiver. A harmless ignored event and an unsupported event required for fulfilment deserve different visibility.
Deploy compatible changes in stages when the contract allows it. Prepare the receiver for the new shape, update the subscription or sender, and then remove obsolete handling after the transition is verified. Keep the ability to investigate messages delivered during the overlap.
Include subscription checks in operational handover. A valid endpoint that is no longer subscribed to the required event will appear quiet rather than broken. Reconciliation and an expected-activity check can reveal that condition before a customer reports it.
Estimate capacity from bursts, not only daily totals
A business may receive modest daily volume but experience a concentrated burst after a promotion or a provider recovers from an outage. The receiving boundary should absorb the expected burst without requiring every downstream action to happen immediately.
Size and test the queue and workers around realistic concurrency. Identify which dependencies restrict throughput and apply backpressure rather than allowing a surge to exhaust connection pools or overload the warehouse API.
Plan storage for retry history and retained payloads as well as successful events. Define when diagnostic material can be removed and what minimal business audit remains. Keeping everything forever is rarely a useful substitute for an explicit retention design.
Review backlog-drain time during testing. If a one-hour interruption takes the rest of the day to recover, the integration may miss its business deadline even though its steady-state performance looks adequate.
Introduce the integration in a controlled slice
Begin with one event and one downstream outcome. For example, record confirmed payments against existing orders before extending the integration into inventory reservation, shipping, and customer messaging. Each additional action creates another boundary to recover across.
Run an initial observation phase when feasible: receive and classify events while comparing proposed actions with existing operations. This reveals unexpected event types and mapping gaps without immediately changing the warehouse's workload.
Set a release gate based on outcome quality, recoverability, and staff readiness. Confirm that the endpoint is verified, duplicate effects are prevented, failures are visible, and reconciliation identifies intentionally introduced missing work. A working demonstration alone is a weak release criterion.
Your first practical document can be a single event contract: what happened, who owns the source fact, what action is allowed, how duplicates are handled, and who resolves exceptions. That document gives engineering and operations a shared definition of success before the first webhook reaches production.
Author
With over 15 years of diverse experience spanning front-end and back-end development, UI/UX design, project management, integration, testing, and ongoing support for business applications, I specialize in transforming ideas into seamless digital solutions. I’m committed to leveraging my expertise to drive innovation and contribute meaningfully to the tech community.