


| Author: Abdullah Ahmed | Category: Content Management System Development
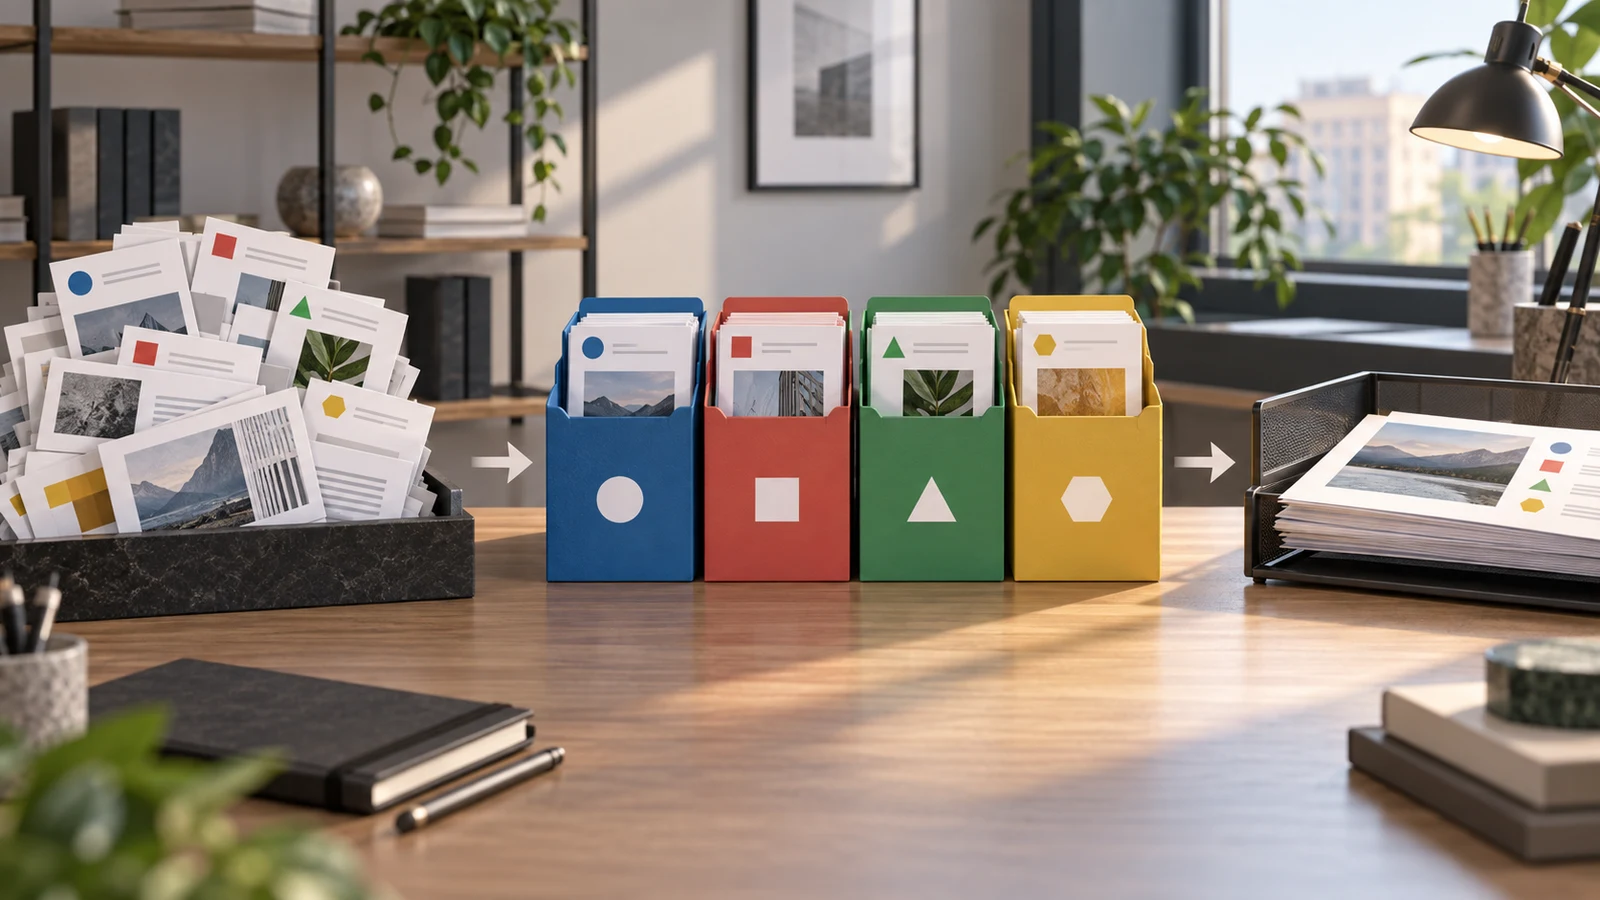
Search results become unreliable long before a content team notices a taxonomy problem. One editor tags an article “customer service,” another uses “support,” and an automated import adds “client help.” Readers see fragmented collections, while the CMS contains several labels for almost the same idea.
AI can help classify content and suggest tags across a large library. It can also amplify inconsistency if the system is allowed to invent categories freely or treat classification as publication approval. The useful design begins with a controlled vocabulary, clear category meanings, and a workflow that separates proposed metadata from live content changes.
Consider a professional-services website with articles, case studies, service pages, and downloadable guides. The team wants better discovery and less repetitive tagging. The following approach explains how to build that capability without turning the content library into a collection of model-generated labels nobody owns.
Decide which discovery problem the tags should solve
Tags can support search filters, related-content suggestions, editorial reporting, navigation, or internal review. These uses may require different levels of precision. A label used only for internal analysis has different consequences from a category that controls a public landing page.
Identify the reader's task. Someone looking for integration advice may benefit from a topic filter, while a buyer comparing services may need content organised by business problem or product stage. More tags do not automatically make either journey easier.
Inspect current failures through real queries and content examples. Look for missing relevant results, irrelevant recommendations, and pages that appear in contradictory collections. This gives the classification project an outcome beyond filling empty metadata fields.
Write down where each field is consumed. If a category also determines URL structure, access, or publication routing, an automatic change may have effects beyond discovery. Those dependencies should influence the approval process.
Give concepts stable identities and clear definitions
A taxonomy needs more than a list of words. Define each concept, its intended scope, examples, exclusions, and relationships to other concepts. Use a stable identifier so a label can change without breaking every content association.
The W3C SKOS Primer explains concepts, preferred and alternative labels, and broader or narrower relationships. You do not need to adopt its full technical representation to benefit from separating a concept's identity from the words used to describe it.
For example, support and customer service might be alternative labels for one concept, while technical support is a narrower concept. The correct relationship depends on your content strategy, not merely on linguistic similarity.
Assign a taxonomy owner who can resolve ambiguous boundaries. Without ownership, every difficult article becomes a reason to create another tag, and the vocabulary gradually loses its value as a shared organising system.
Distinguish topic, format, audience, and lifecycle
A case study is a content format, not a topic. A technical manager is an audience, not a publication state. Storing these dimensions in one undifferentiated tag list makes both classification and user filtering harder to understand.
Create separate fields where the distinctions matter. An article might have a primary topic, optional secondary topics, a format, an intended audience, and an editorial status. Each field should have its own allowed values and selection rules.
Use single selection where the business meaning requires it. A primary service category may need one value, while secondary topics can be multiple. Do not ask the model to choose an arbitrary number of labels because a generic tagging example used that pattern.
Explain the difference in editorial tools. If users cannot distinguish two metadata fields, the model will not repair the underlying ambiguity. Better definitions can improve human and automated classification at the same time.
Prepare representative examples before writing the prompt
Choose content that illustrates clear matches, difficult boundaries, multiple topics, and no suitable category. Have knowledgeable editors label a reference sample and discuss disagreements.
Disagreement is useful evidence. It may indicate a vague definition, overlapping categories, or a genuine editorial choice. Resolve the taxonomy issue before treating the model's answer as an accuracy problem.
Include negative examples. An article mentioning payment technology in passing may still be primarily about user experience. The classifier needs to distinguish the main subject from incidental terms if tags are meant to guide readers to substantial coverage.
Keep the reference set separate from examples used to tune the prompt. Evaluation should include content the team did not optimise around repeatedly. Refresh it as new subjects and content types enter the library.
Ask for bounded proposals with evidence
Give the model the allowed concept identifiers, definitions, and relevant content. Request a structured proposal containing selected concepts and short supporting passages or reasons. Reject unknown identifiers through application validation.
Allow an unresolved result when no category fits or the content is too ambiguous. A forced answer can look complete while routing the page into the wrong collection. Unresolved cases also reveal where the taxonomy may need deliberate extension.
Limit the number of secondary tags according to the discovery design. A model that attaches every related concept makes filters less selective. Require the tag to represent meaningful coverage rather than a word that appears once.
Keep the explanation concise and useful to the reviewer. A cited paragraph that demonstrates the article's focus is more actionable than a long general justification. The aim is to help editors assess the proposal efficiently.
Validate structure separately from editorial meaning
Application checks should confirm that identifiers exist, required fields are present, cardinality rules are met, and prohibited combinations are absent. These are deterministic properties and should not depend on the model's self-assessment.
Semantic review asks whether the selected categories represent the content accurately. A structurally valid proposal can still be wrong. Keep those two results distinct so editors know whether they are fixing formatting or making a classification decision.
Check the content version used for classification. If an editor substantially rewrites the article while the job runs, the proposal may no longer apply. Store the revision identifier and compare it before accepting the metadata.
Define behaviour for incomplete extraction or unavailable source text. The system should not classify an empty document based only on its title unless that is an explicitly supported mode with appropriate limitations.
Choose review rules based on the metadata's effect
A low-consequence internal tag may be eligible for automatic application after adequate evaluation. A category that changes public navigation, redirects, or review ownership may need a different gate.
Base that policy on measured performance and business impact. Do not use an unexplained model-generated confidence number as the sole reason to publish a change. Evidence from representative labelled examples is more useful for choosing the initial boundary.
Present changed metadata alongside its effect. An editor should know if accepting a category will move the page into a public collection or notify another team. Hidden side effects make even a correct label difficult to approve responsibly.
Support efficient batch review without encouraging blind acceptance. Group similar proposals, show exceptions clearly, and allow inspection of source passages. Preserve the reviewer's corrections as versioned decisions.
Keep tagging and publication as separate operations
A classifier may determine that a draft concerns API integration. That does not establish that the article is accurate, complete, approved, or ready for release. Publication conditions should remain part of the CMS workflow.
Run required content checks independently: approved revision, valid schedule, required assets, ownership, and any content-specific review. The publishing service should enforce them even if the classification job requests release.
If classification selects a reviewer, validate that the person or role is eligible. Do not let the model invent an approver or bypass a required specialist because the chosen category seems routine.
Record classification and publication outcomes separately. A page can be correctly tagged but blocked from publication, or published while a secondary tagging improvement remains pending. Clear states make the queue easier to operate.
Migrate an existing library in inspectable batches
Before changing thousands of records, export a mapping of existing metadata and preserve a way to compare old and proposed values. Identify pages whose categories influence URLs, feeds, or prominent navigation.
Start with a bounded collection and review both individual accuracy and collection-level behaviour. A classifier may look reasonable article by article while assigning almost everything to one broad category, making the resulting landing page less useful.
Use a batch reference and per-item status. Failed records should not disappear inside an overall completed job. Make retries safe so they do not overwrite later human edits or duplicate associations.
Define rollback as a metadata operation with a version check. Restoring the pre-batch value is appropriate only if no newer valid decision should be preserved. The rollback process needs the same respect for concurrent editing as the original update.
Handle synonyms and multilingual labels deliberately
Readers may search with different terms from those used in the preferred label. Alternative labels and search mappings can help without creating separate concepts for every phrase.
For multilingual content, distinguish translating a label from deciding that two concepts are equivalent. A literal translation may not match the terminology used by the intended audience. Involve reviewers who understand the language and subject.
Store language-specific labels against the same stable concept when the meaning is shared. If regional business meanings differ, document that distinction instead of forcing a false equivalence.
Evaluate classification across languages separately. Strong performance on English articles does not establish equivalent quality on another language, especially when the taxonomy examples and definitions were written only in English.
Measure the resulting discovery experience
Classification accuracy is an intermediate measure. Check whether relevant pages become easier to find, filters remain selective, and related-content components offer useful suggestions. Use representative reader tasks and inspect actual query behaviour where available.
Measure false inclusions and missed relevant items separately. A category can look populated while containing distracting results; another can appear tidy because important pages were never assigned to it.
Review coverage by content type and age. Older articles may use different terminology or incomplete metadata. Decide whether they need reclassification, editorial revision, or retirement rather than applying new labels indiscriminately.
Keep an editorial feedback channel tied to the specific concept and content item. Reports such as wrong primary category or missing narrower topic are easier to act on than a generic rating of the AI feature.
Maintain the taxonomy as the organisation changes
New services and changing audiences can make an earlier vocabulary inadequate. Review requests for new concepts through the taxonomy owner, with examples of content that existing concepts cannot represent well.
When merging or retiring concepts, preserve mappings and inspect downstream consumers. Search filters, saved queries, analytics reports, and public collections may depend on the old identifiers.
Version definitions when changes alter classification meaning. A model evaluated against one version should not silently apply a different interpretation later. Keep the taxonomy version with the classification job and evaluation results.
Schedule targeted reclassification when the vocabulary changes. Reprocessing only affected collections can reduce cost and review work compared with regenerating every tag across the entire site.
Control source access and operational cost
A tagging task should receive only the content it is authorised to process. Drafts, internal documents, and restricted case studies may require different access paths from public articles. Keep diagnostic output from becoming an uncontrolled archive of unpublished material.
Treat content text as input data rather than an instruction channel. An imported page should not be able to expand the classifier's tool access or request publication outside the CMS policy.
Track processing and review cost per accepted record. Long documents, repeated retries, and verbose outputs can increase expense without improving classification. Test whether a relevant excerpt is sufficient while preserving enough context for accurate topic selection.
Provide a pause mechanism and a visible backlog. Editors should be able to continue manual classification if the service is unavailable, then resume automation from recorded state when it returns.
## Inspect collection balance before accepting a batch
After classifying a pilot collection, review the distribution of assignments. A broad category absorbing nearly every article may indicate vague definitions, while a rarely used category may be too narrow or poorly explained. Neither pattern proves an error by itself, but both deserve inspection.
Open representative pages from each group and ask whether a reader would understand why they belong together. This qualitative check complements record-level labels and can expose a taxonomy that is technically consistent but unhelpful in navigation.
Check articles with several secondary topics. If the same combinations recur, the content model may need a clearer distinction between primary purpose and supporting subject matter. Avoid solving every ambiguity by attaching more tags.
Preserve the reviewed distribution as a reference for later changes. A sudden shift after a model update can then be investigated against the content mix and taxonomy version rather than dismissed as ordinary variation.
Keep generated labels out of access decisions
A topic classification should not become an authority to expose restricted content. Public visibility belongs to the CMS's access and publication model, even if the taxonomy contains audience or confidentiality-related labels.
If metadata helps route a restricted draft, validate the destination and recipient permissions independently. A wrong classification must not reveal the document to an unauthorised group.
Test that separation with deliberately incorrect proposals. It should remain impossible for a classifier to make private material public merely by assigning a public-facing category.
Make one collection demonstrably better
Choose a collection whose discovery problems are visible, define a small controlled vocabulary, and label a representative sample. Build proposals that editors can inspect and apply without losing ownership of the content.
Compare the resulting collection with the original using real reader tasks. If the labels are more consistent but navigation remains confusing, revise the discovery design instead of adding more tags.
A successful first release leaves the team with clear concepts, reviewable decisions, and an improvement readers can experience. Automation then supports a maintained content model rather than creating an ever-growing vocabulary that nobody can explain.
Author
With over 15 years of diverse experience spanning front-end and back-end development, UI/UX design, project management, integration, testing, and ongoing support for business applications, I specialize in transforming ideas into seamless digital solutions. I’m committed to leveraging my expertise to drive innovation and contribute meaningfully to the tech community.